Ami Baid
I recently graduated from UT Austin with degrees in computer science and math as a Turing Scholar. During undergrad, I was a researcher in the UT Austin Computer Vision Lab, advised by Prof. Kristen Grauman. I'll be starting my Master's in CS at Stanford this fall🌲
My research focuses on audio-visual perception and generation. Recently, I've been working on improving how language models ground their outputs in information from diverse modalities.
Research

Personal Visual Context Learning in Large Multimodal Models
arXiv 2026 [paper] [project page]
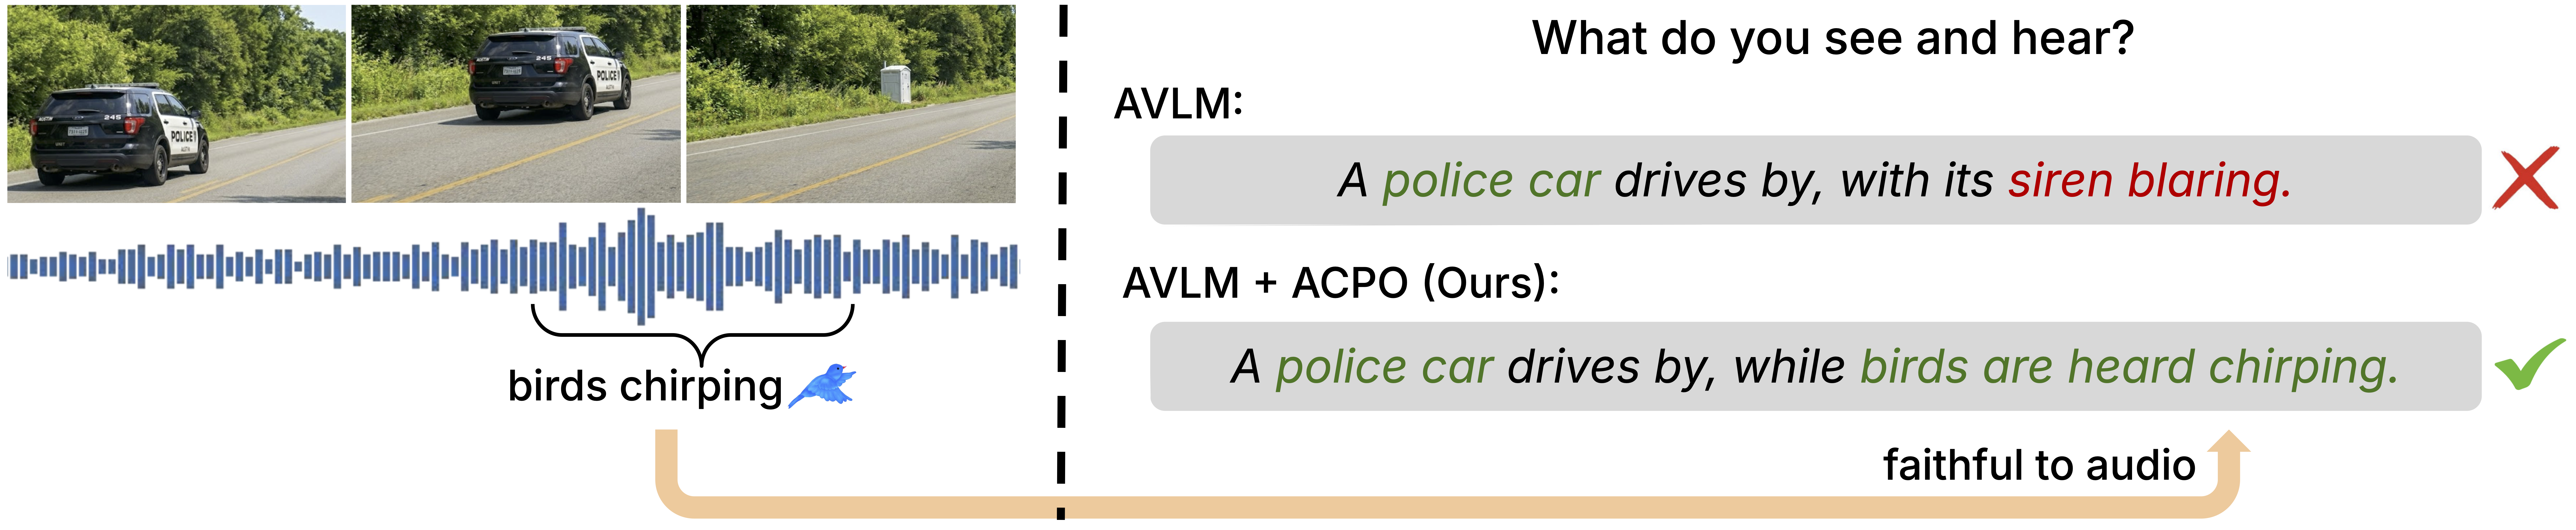
Don't Let the Video Speak: Audio-Contrastive Preference Optimization for Audio-Visual Language Models
ECCV 2026 [paper] [project page]
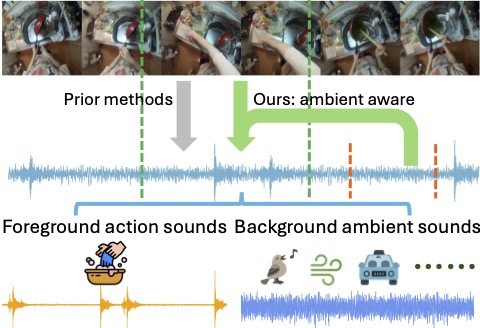
Action2Sound: Ambient-Aware Generation of Action Sounds from Egocentric Videos
ECCV 2024, Oral [paper] [project page]
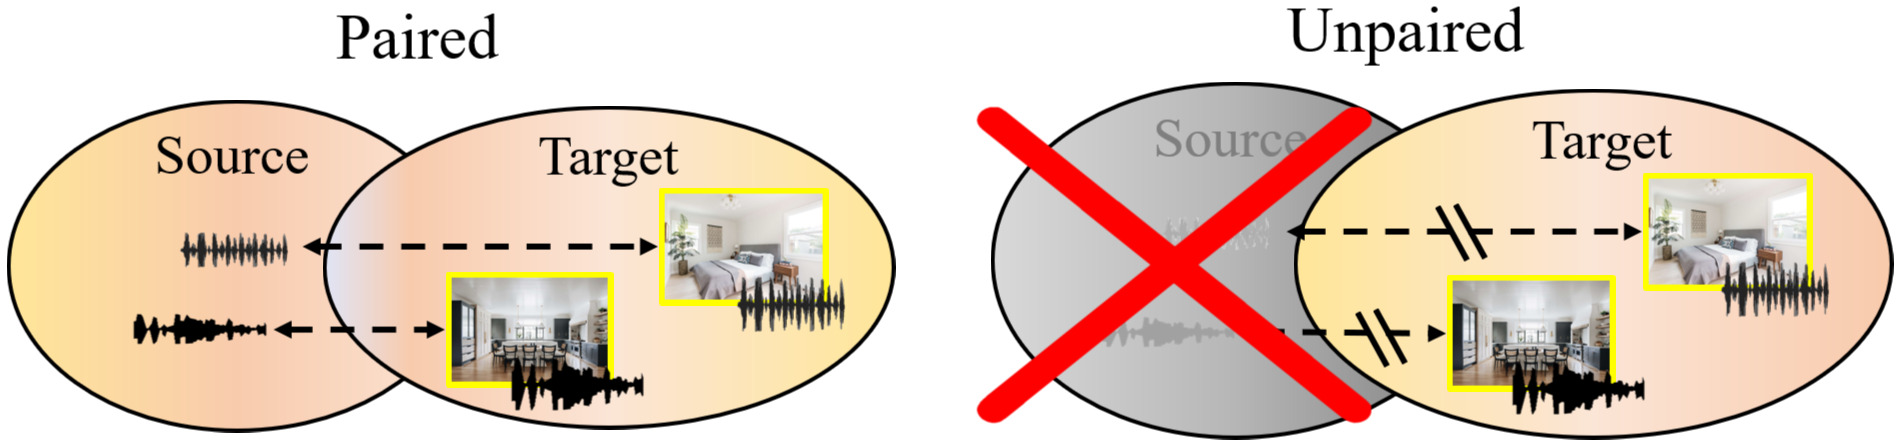
Self-Supervised Visual-Acoustic Matching (acknowledged)
NeurIPS 2023 [paper] [project page]
Internships
- Software engineering intern @ Stripe (summer 2025): added a visual modality to Stripe's LLM-based Terms-of-Service evaluation system.
- Software engineering intern @ Salesforce (summer 2024): automated workflows on Salesforce's internal Temporal.io platform; contributed to the open-source Terraform Temporal provider.
Other Projects
- Gaze-centered Egocentric Video Representations: a preprocessing pipeline that reallocates video resolution around the wearer's gaze, improving efficiency in egocentric video QA. [GitHub]